Introduction to Statistical Software
Lecture 7
Farmingdale State College
Statistical Software
Excel, R, SPSS – Oh My!
There are several tools you can use for statistical analyses.
PSY 360 (Research Methods) typically employs the use of both Excel and SPSS
I think the best approach is to use these options in addition to free software such as R.
Statistical Software
The Menu
table_chart
Excel
Familiar, and good for the core concepts
code
R
Free, flexible, runs in a browser
analytics
SPSS
Point-and-click, with a syntax editor
Statistical Software
R
R is available on all Operating Systems completely free of charge and can even be accessed through web browsers such as Safari, Chrome, or Mozilla Firefox.
As an added bonus, R is even accessible in this presentation!
Press ~` (no Shift needed) to open R.
Script (top) is where you write code. Console (bottom) is where R answers.
Statistical Software
Why should I care?
Your time is worth something and if I can show you a different way of approaching statistical questions that you might find easier—I will do whatever I can to do so!
Your future job might not have SPSS
You can learn programming syntax and troubleshoot in real-time
Statistical Software
Excel
We have used Microsoft Excel in this course to demonstrate core concepts such as finding the arithmetic average, standard deviation, measures of central tendency, and calculating z-scores.
- Since statistical tests are mathematical at a base-level, nearly any test that can be run elsewhere can be run in Excel
Statistical Software
Excel: Data Analysis Toolpak
Excel has first-party addons such as the Data Analysis Toolpak (and third-party ones too). The Data Analysis Toolpak can run the following tests:
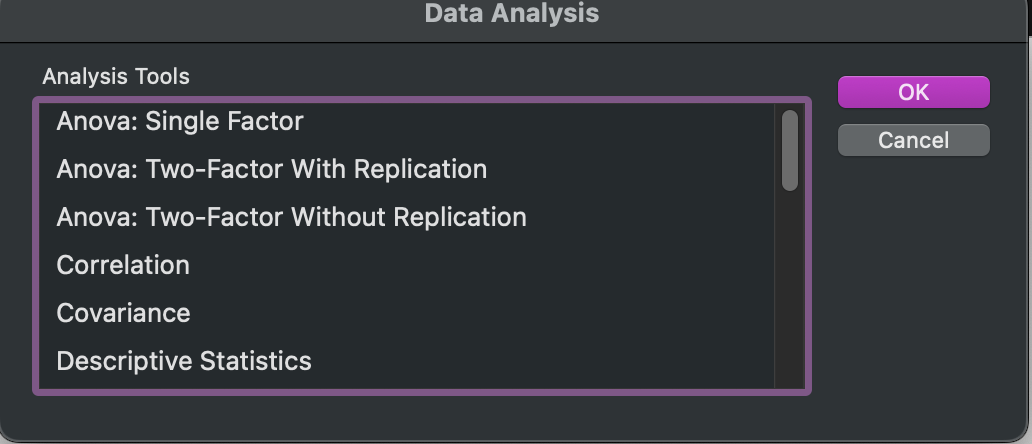
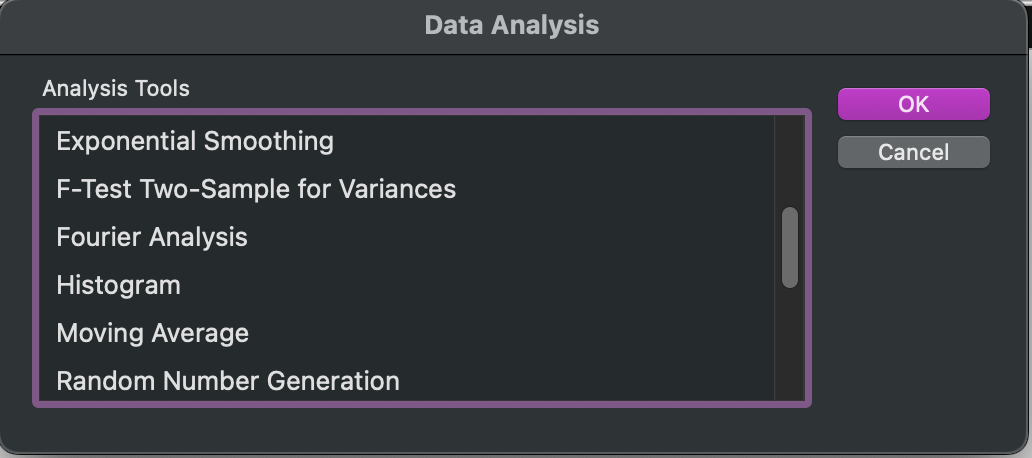
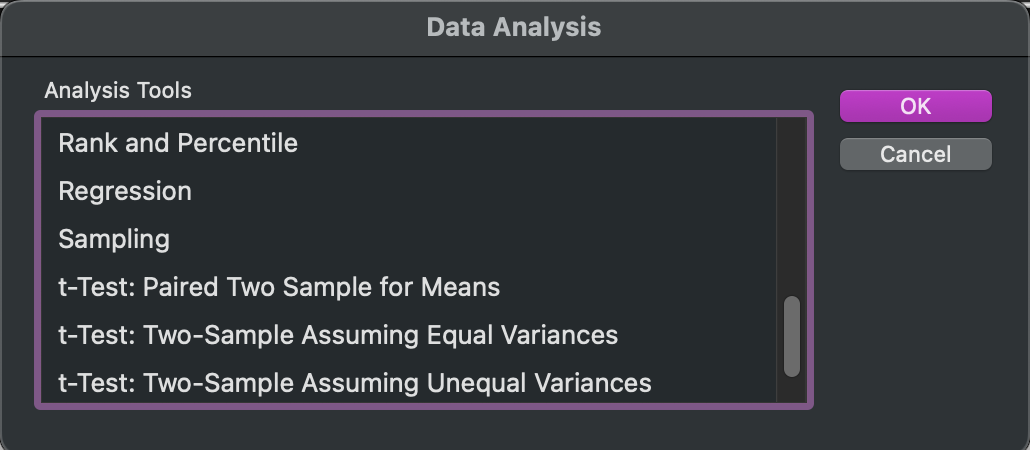
Whoa! Those are a lot of tests! Excel is an absolute powerhouse, but some of the tests and options are somewhat difficult to access and/or have a steep learning curve.
Statistical Software
SPSS
- SPSS
- Statistical Package for the Social Sciences. Used in a variety of disciplines, with options for the majority of tests you will end up running in your academic career, plus a syntax editor that gives you more control over your data, tests, and outputs.
Statistical Software
SPSS: Example
Let’s walk through an example in SPSS step-by-step.
Setup
- Download the dataset
movie_dat_trimmed.csvfrom Brightspace - Double-click on IBM SPSS, then open the file
SPSS: Example
Descriptive Statistics
SPSS does its best to analyze your data and assign data value types (continuous, nominal) as well as scales of measurement (nominal, ordinal, interval, ratio).
SPSS will only allow specific data types to be analyzed in specific ways
SPSS does not always ‘know’ what you are looking for, so you need to make sure your data is set up correctly!
SPSS: Example
Two Views
SPSS has two views.
- Variable View
- An overview of your variables.
- Data View
- A glimpse of your raw data.
SPSS: Example
Two Views: What to Look For
Variable View
- What is the name?
- What is the data type?
- What is the range of values?
- Are there any labels?
- What is the Measure type?
Data View
- What is in the first column?
- What is in the second column?
- etc.
SPSS: Example
Descriptive Statistics
Descriptive Statistics describe the data, they give us an idea of where our data (likely) comes from, the measures of central tendency, and estimation about normality can be made.
Mean | Sum
Standard Deviation
Range
Mode
Kurtosis*
Skewness*
* Kurtosis and skewness help us judge how close to normal our data is.
SPSS: Example
Frequency Statistics
Frequency Statistics give us an idea of the composition of our dataset and allow us to make estimations and guesses in relation to the normality of our data
Frequency of Responses (% or n)
Minimum Values
Max Values
Range
SPSS: Example
Your Turn
Descriptive and Frequency Statistics
In our dataset, we want to investigate the categorical composition of our data as well as the statistical makeup of our data.
For the dataset provided, find the descriptive statistics and frequency statistics for each variable of the appropriate data type.
Statistical Software | ⬡⬢⬡⬢⬡⬢